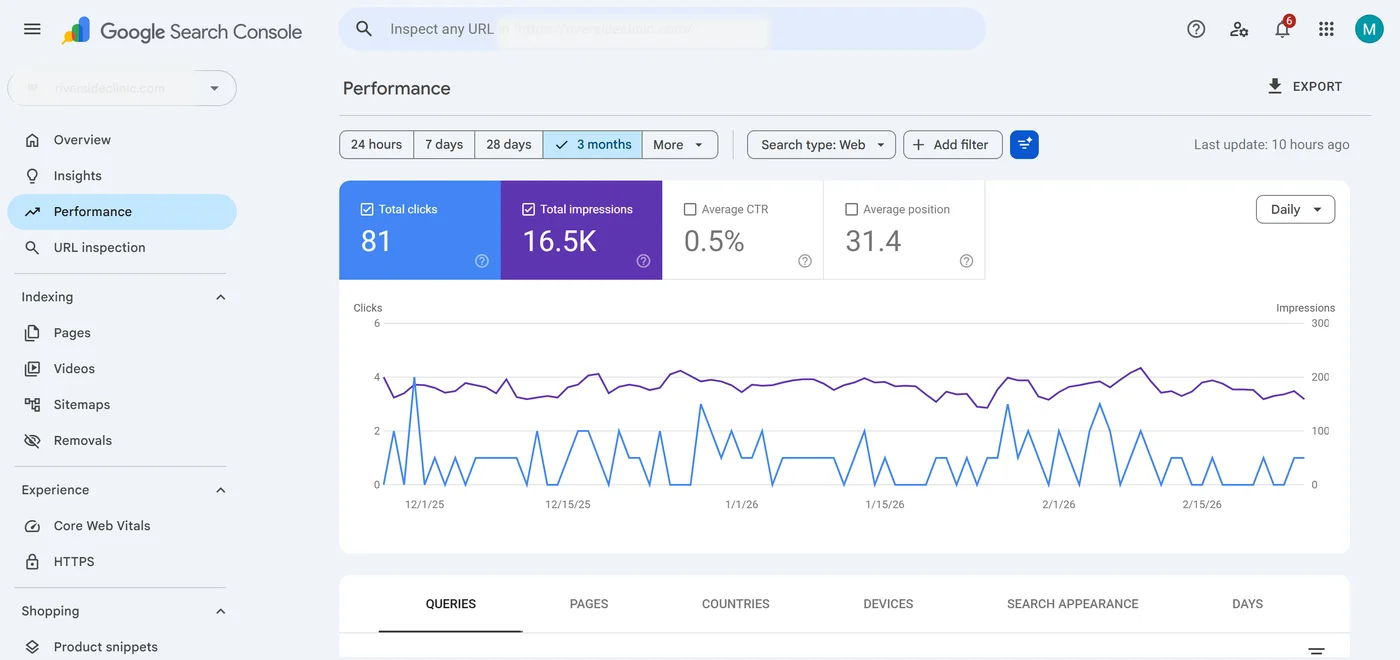
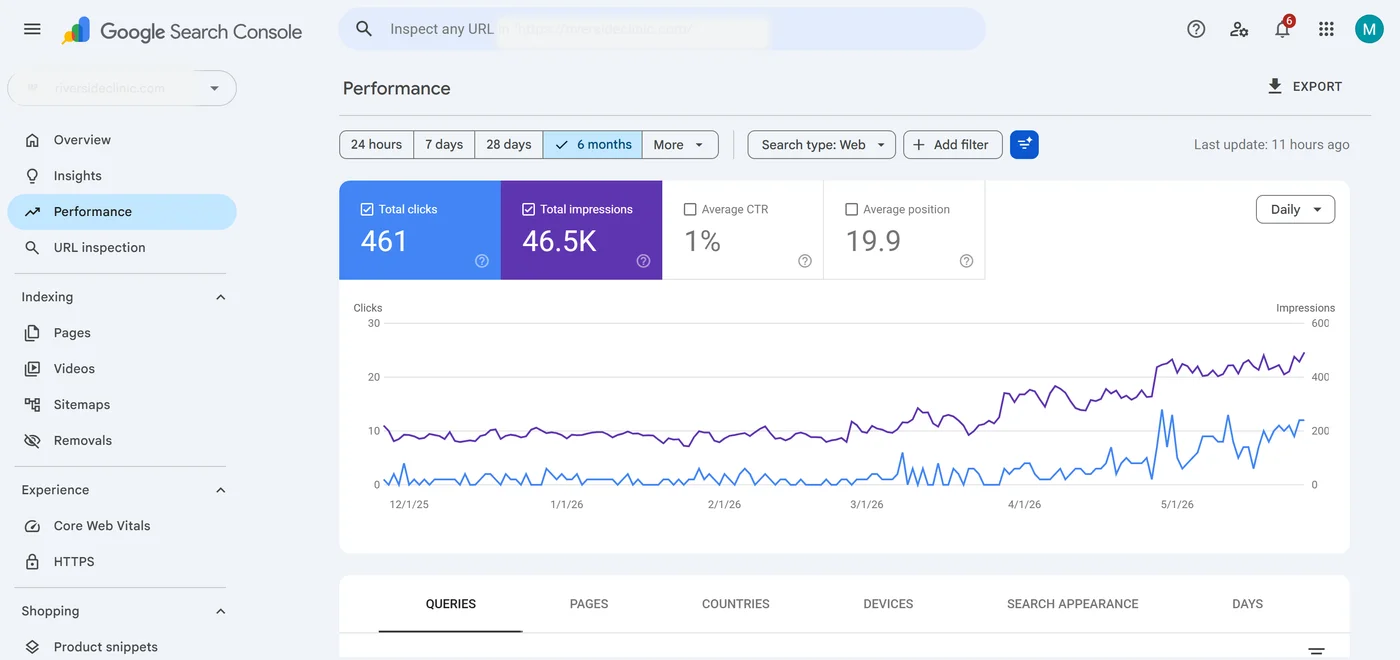
We sequenced the work deliberately. Publishing content onto a site with cannibalization and crawl problems wastes the content, so the foundation came first.
Stage one: technical cleanup and page ownership
Our technical sprint ran across months one to three: crawl and indexation triage, canonical and redirect cleanup, template-level duplication fixes, Core Web Vitals and renderability checks, and internal status-code and schema validation. The outcome we were after was a cleaner indexed-page ratio and less crawl waste on low-value URLs, so that ranking signals could concentrate on the pages that matter. In parallel we mapped every target query to a single intended page and a single intent, which exposed exactly where multiple URLs were fighting each other.
Stage two: useful supporting content
This is the heart of the engagement, because our flagship service is informational content and it is what did the heavy lifting. We built out 15 articles across 6 topic clusters, structured as a hub-and-spoke system feeding the commercial pages. For a barbershop, the clusters map to how customers actually think: haircut styles and grooming guides, beard care and maintenance, pricing and what a cut costs, appointment and walk-in logistics, and men's hair care advice, with a local shop-selection cluster tying it together.
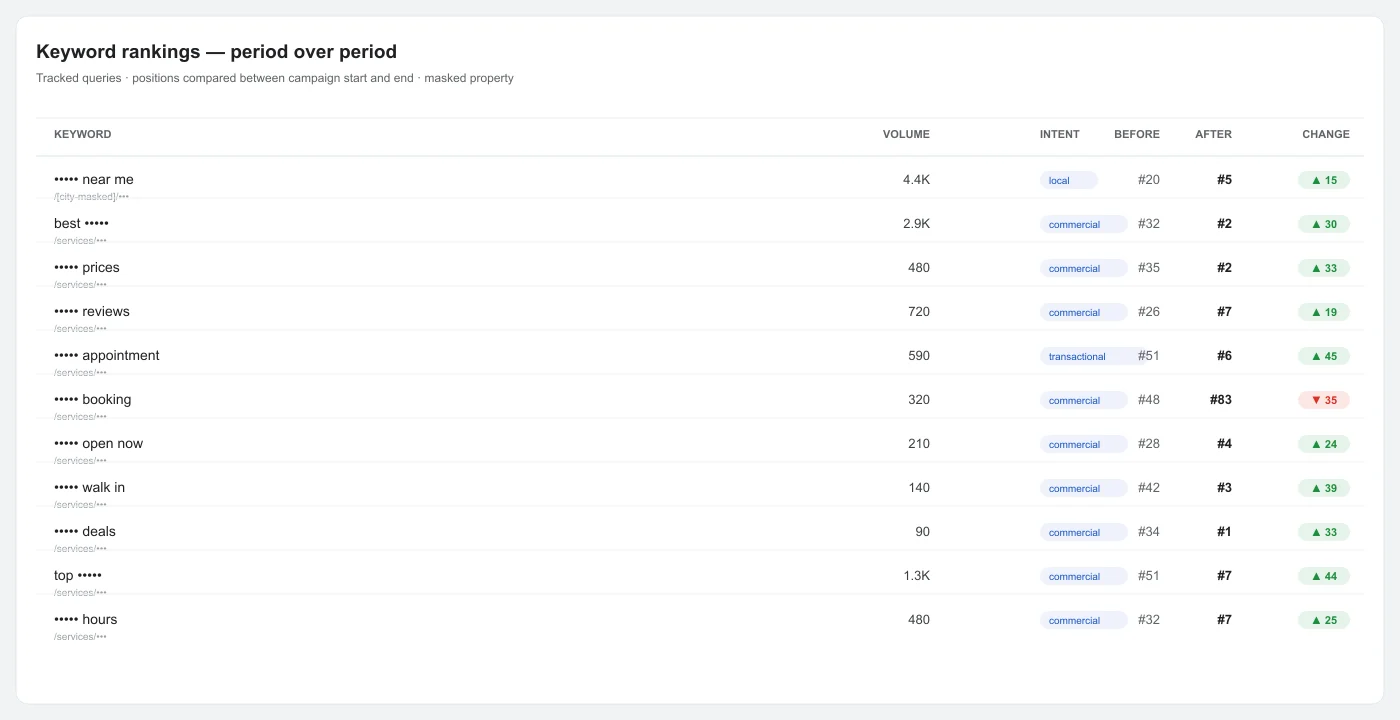
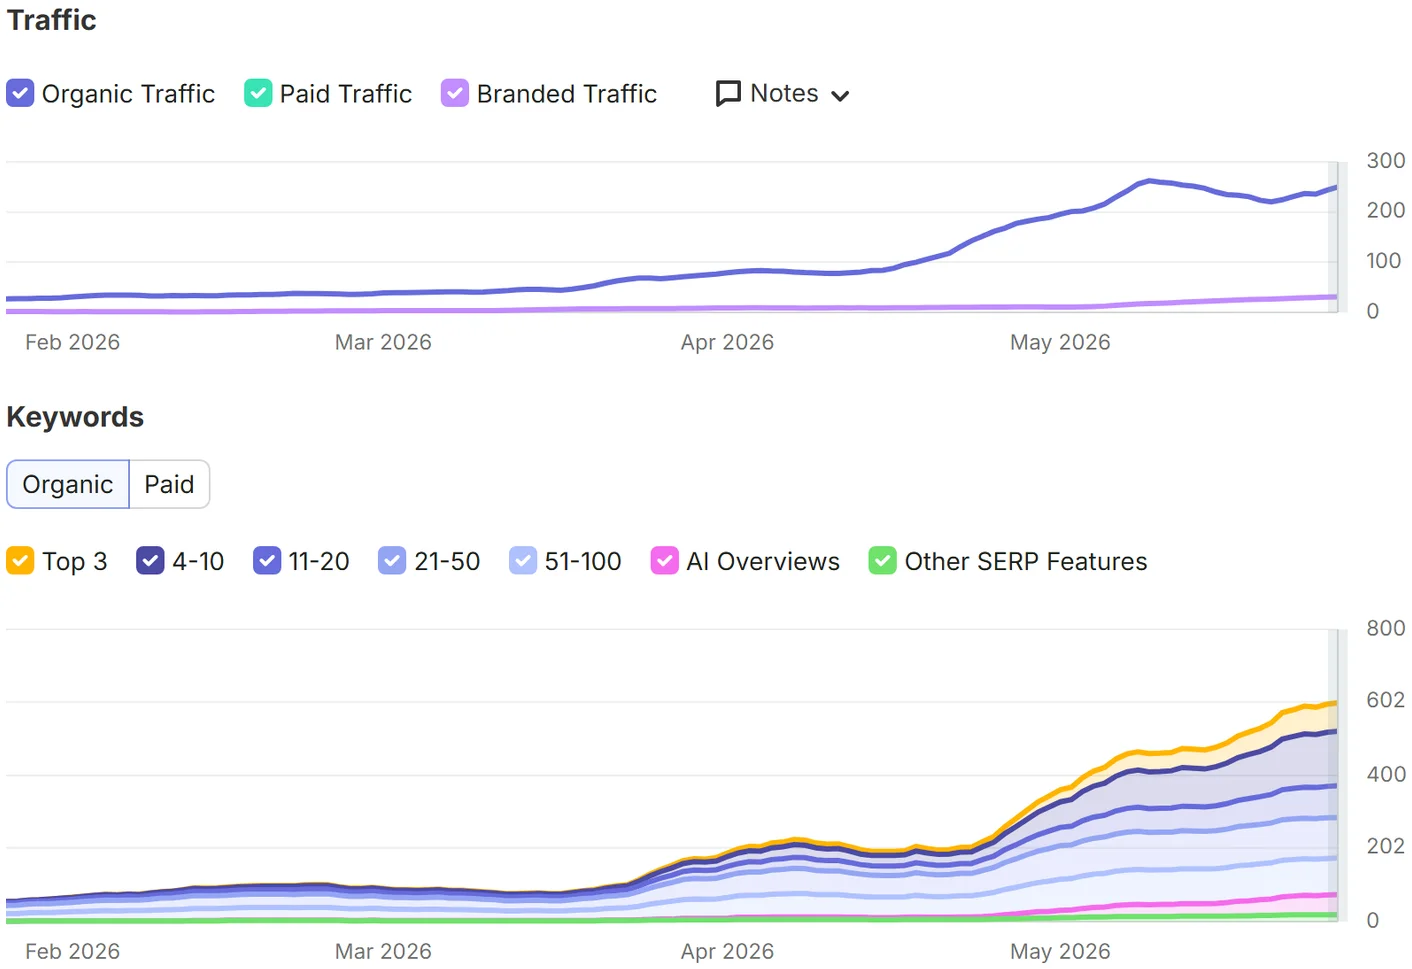
The mechanism matters more than the count. A well-structured body of informational content can earn topical authority and, just as importantly, creates internal links with relevant anchors pointing at the money pages. By the end of the engagement the site reached 122 informational keywords and our topical authority index moved from 28 to 61. That index rising is the leading indicator; the money-page rankings lifting is the lagging effect. In this engagement, content led and rankings followed.
Stage three: architecture and internal linking
Running months two to four, this workstream turned the content into ranking pressure: hub-and-spoke mapping, deliberate anchor-text distribution, cannibalization consolidation, shorter click paths to the conversion pages, and pruning of orphan and weak pages. This is where the money pages became easy to reach and started to hold their positions instead of bouncing around.
Entity clarity, structured data, and editorial QA
In months three and four we cleaned up Organization and Service schema, aligned author and reviewer entities, checked citation consistency, and built answer-ready summary blocks written to be quotable by AI assistants without making claims the pages could not support. Brand Voice and editorial QA ran alongside from the start, sampling approved pages to set tone and claim boundaries so nothing risky reached publication. Given the no-fake-claims constraint, that guardrail was not optional.
Data sources throughout were Google Search Console for impressions, clicks, CTR and position, analytics for sessions and conversions, and a third-party tool for Domain Rating, referring domains and visibility. Attribution for bookings is modeled on an average ticket.